Pre-Winter Sale 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: best70

Professional-Machine-Learning-Engineer Google Professional Machine Learning Engineer Questions and Answers

Questions 4

You have trained a text classification model in TensorFlow using Al Platform. You want to use the trained model for batch predictions on text data stored in BigQuery while minimizing computational overhead. What should you do?

Options:

A.

Export the model to BigQuery ML.

B.

Deploy and version the model on Al Platform.

C.

Use Dataflow with the SavedModel to read the data from BigQuery

D.

Submit a batch prediction job on Al Platform that points to the model location in Cloud Storage.

Buy Now
Questions 5

You developed a Transformer model in TensorFlow to translate text Your training data includes millions of documents in a Cloud Storage bucket. You plan to use distributed training to reduce training time. You need to configure the training job while minimizing the effort required to modify code and to manage the clusters configuration. What should you do?

Options:

A.

Create a Vertex Al custom training job with GPU accelerators for the second worker pool Use tf .distribute.MultiWorkerMirroredStrategy for distribution.

B.

Create a Vertex Al custom distributed training job with Reduction Server Use N1 high-memory machine type instances for the first and second pools, and use N1 high-CPU machine type instances for the third worker pool.

C.

Create a training job that uses Cloud TPU VMs Use tf.distribute.TPUStrategy for distribution.

D.

Create a Vertex Al custom training job with a single worker pool of A2 GPU machine type instances Use tf .distribute.MirroredStraregy for distribution.

Buy Now
Questions 6

You work on a team that builds state-of-the-art deep learning models by using the TensorFlow framework. Your team runs multiple ML experiments each week which makes it difficult to track the experiment runs. You want a simple approach to effectively track, visualize and debug ML experiment runs on Google Cloud while minimizing any overhead code. How should you proceed?

Options:

A.

Set up Vertex Al Experiments to track metrics and parameters Configure Vertex Al TensorBoard for visualization.

B.

Set up a Cloud Function to write and save metrics files to a Cloud Storage Bucket Configure a Google Cloud VM to host TensorBoard locally for visualization.

C.

Set up a Vertex Al Workbench notebook instance Use the instance to save metrics data in a Cloud Storage bucket and to host TensorBoard locally for visualization.

D.

Set up a Cloud Function to write and save metrics files to a BigQuery table. Configure a Google Cloud VM to host TensorBoard locally for visualization.

Buy Now
Questions 7

You are developing an ML model that uses sliced frames from video feed and creates bounding boxes around specific objects. You want to automate the following steps in your training pipeline: ingestion and preprocessing of data in Cloud Storage, followed by training and hyperparameter tuning of the object model using Vertex AI jobs, and finally deploying the model to an endpoint. You want to orchestrate the entire pipeline with minimal cluster management. What approach should you use?

Options:

A.

Use Kubeflow Pipelines on Google Kubernetes Engine.

B.

Use Vertex AI Pipelines with TensorFlow Extended (TFX) SDK.

C.

Use Vertex AI Pipelines with Kubeflow Pipelines SDK.

D.

Use Cloud Composer for the orchestration.

Buy Now
Questions 8

You are training a TensorFlow model on a structured data set with 100 billion records stored in several CSV files. You need to improve the input/output execution performance. What should you do?

Options:

A.

Load the data into BigQuery and read the data from BigQuery.

B.

Load the data into Cloud Bigtable, and read the data from Bigtable

C.

Convert the CSV files into shards of TFRecords, and store the data in Cloud Storage

D.

Convert the CSV files into shards of TFRecords, and store the data in the Hadoop Distributed File System (HDFS)

Buy Now
Questions 9

Your organization wants to make its internal shuttle service route more efficient. The shuttles currently stop at all pick-up points across the city every 30 minutes between 7 am and 10 am. The development team has already built an application on Google Kubernetes Engine that requires users to confirm their presence and shuttle station one day in advance. What approach should you take?

Options:

A.

1. Build a tree-based regression model that predicts how many passengers will be picked up at each shuttle station.

2. Dispatch an appropriately sized shuttle and provide the map with the required stops based on the prediction.

B.

1. Build a tree-based classification model that predicts whether the shuttle should pick up passengers at each shuttle station.

2. Dispatch an available shuttle and provide the map with the required stops based on the prediction

C.

1. Define the optimal route as the shortest route that passes by all shuttle stations with confirmed attendance at the given time under capacity constraints.

2 Dispatch an appropriately sized shuttle and indicate the required stops on the map

D.

1. Build a reinforcement learning model with tree-based classification models that predict the presence of passengers at shuttle stops as agents and a reward function around a distance-based metric

2. Dispatch an appropriately sized shuttle and provide the map with the required stops based on the simulated outcome.

Buy Now
Questions 10

Your company manages a video sharing website where users can watch and upload videos. You need to

create an ML model to predict which newly uploaded videos will be the most popular so that those videos can be prioritized on your company’s website. Which result should you use to determine whether the model is successful?

Options:

A.

The model predicts videos as popular if the user who uploads them has over 10,000 likes.

B.

The model predicts 97.5% of the most popular clickbait videos measured by number of clicks.

C.

The model predicts 95% of the most popular videos measured by watch time within 30 days of being

uploaded.

D.

The Pearson correlation coefficient between the log-transformed number of views after 7 days and 30 days after publication is equal to 0.

Buy Now
Questions 11

You are an ML engineer at an ecommerce company and have been tasked with building a model that predicts how much inventory the logistics team should order each month. Which approach should you take?

Options:

A.

Use a clustering algorithm to group popular items together. Give the list to the logistics team so they can increase inventory of the popular items.

B.

Use a regression model to predict how much additional inventory should be purchased each month. Give the results to the logistics team at the beginning of the month so they can increase inventory by the amount predicted by the model.

C.

Use a time series forecasting model to predict each item ' s monthly sales. Give the results to the logistics team so they can base inventory on the amount predicted by the model.

D.

Use a classification model to classify inventory levels as UNDER_STOCKED, OVER_STOCKED, and CORRECTLY_STOCKED. Give the report to the logistics team each month so they can fine-tune inventory levels.

Buy Now
Questions 12

You are developing a custom image classification model in Python. You plan to run your training application on Vertex Al Your input dataset contains several hundred thousand small images You need to determine how to store and access the images for training. You want to maximize data throughput and minimize training time while reducing the amount of additional code. What should you do?

Options:

A.

Store image files in Cloud Storage and access them directly.

B.

Store image files in Cloud Storage and access them by using serialized records.

C.

Store image files in Cloud Filestore, and access them by using serialized records.

D.

Store image files in Cloud Filestore and access them directly by using an NFS mount point.

Buy Now
Questions 13

You are developing a model to help your company create more targeted online advertising campaigns. You need to create a dataset that you will use to train the model. You want to avoid creating or reinforcing unfair bias in the model. What should you do?

Choose 2 answers

Options:

A.

Include a comprehensive set of demographic features.

B.

include only the demographic groups that most frequently interact with advertisements.

C.

Collect a random sample of production traffic to build the training dataset.

D.

Collect a stratified sample of production traffic to build the training dataset.

E.

Conduct fairness tests across sensitive categories and demographics on the trained model.

Buy Now
Questions 14

You work for a large retailer and you need to build a model to predict customer churn. The company has a dataset of historical customer data, including customer demographics, purchase history, and website activity. You need to create the model in BigQuery ML and thoroughly evaluate its performance. What should you do?

Options:

A.

Create a linear regression model in BigQuery ML and register the model in Vertex Al Model Registry Evaluate the model performance in Vertex Al.

B.

Create a logistic regression model in BigQuery ML and register the model in Vertex Al Model Registry. Evaluate the model performance in Vertex Al.

C.

Create a linear regression model in BigQuery ML Use the ml. evaluate function to evaluate the model performance.

D.

Create a logistic regression model in BigQuery ML Use the ml.confusion_matrix function to evaluate the model performance.

Buy Now
Questions 15

You are profiling the performance of your TensorFlow model training time and notice a performance issue caused by inefficiencies in the input data pipeline for a single 5 terabyte CSV file dataset on Cloud Storage. You need to optimize the input pipeline performance. Which action should you try first to increase the efficiency of your pipeline?

Options:

A.

Preprocess the input CSV file into a TFRecord file.

B.

Randomly select a 10 gigabyte subset of the data to train your model.

C.

Split into multiple CSV files and use a parallel interleave transformation.

D.

Set the reshuffle_each_iteration parameter to true in the tf.data.Dataset.shuffle method.

Buy Now
Questions 16

You created a model that uses BigQuery ML to perform linear regression. You need to retrain the model on the cumulative data collected every week. You want to minimize the development effort and the scheduling cost. What should you do?

Options:

A.

Use BigQuerys scheduling service to run the model retraining query periodically.

B.

Create a pipeline in Vertex Al Pipelines that executes the retraining query and use the Cloud Scheduler API to run the query weekly.

C.

Use Cloud Scheduler to trigger a Cloud Function every week that runs the query for retraining the model.

D.

Use the BigQuery API Connector and Cloud Scheduler to trigger. Workflows every week that retrains the model.

Buy Now
Questions 17

You work for a company that provides an anti-spam service that flags and hides spam posts on social media platforms. Your company currently uses a list of 200,000 keywords to identify suspected spam posts. If a post contains more than a few of these keywords, the post is identified as spam. You want to start using machine learning to flag spam posts for human review. What is the main advantage of implementing machine learning for this business case?

Options:

A.

Posts can be compared to the keyword list much more quickly.

B.

New problematic phrases can be identified in spam posts.

C.

A much longer keyword list can be used to flag spam posts.

D.

Spam posts can be flagged using far fewer keywords.

Buy Now
Questions 18

You received a training-serving skew alert from a Vertex Al Model Monitoring job running in production. You retrained the model with more recent training data, and deployed it back to the Vertex Al endpoint but you are still receiving the same alert. What should you do?

Options:

A.

Update the model monitoring job to use a lower sampling rate.

B.

Update the model monitoring job to use the more recent training data that was used to retrain the model.

C.

Temporarily disable the alert Enable the alert again after a sufficient amount of new production traffic has passed through the Vertex Al endpoint.

D.

Temporarily disable the alert until the model can be retrained again on newer training data Retrain the model again after a sufficient amount of new production traffic has passed through the Vertex Al endpoint

Buy Now
Questions 19

You work for a bank and are building a random forest model for fraud detection. You have a dataset that

includes transactions, of which 1% are identified as fraudulent. Which data transformation strategy would likely improve the performance of your classifier?

Options:

A.

Write your data in TFRecords.

B.

Z-normalize all the numeric features.

C.

Oversample the fraudulent transaction 10 times.

D.

Use one-hot encoding on all categorical features.

Buy Now
Questions 20

You built and manage a production system that is responsible for predicting sales numbers. Model accuracy is crucial, because the production model is required to keep up with market changes. Since being deployed to production, the model hasn ' t changed; however the accuracy of the model has steadily deteriorated. What issue is most likely causing the steady decline in model accuracy?

Options:

A.

Poor data quality

B.

Lack of model retraining

C.

Too few layers in the model for capturing information

D.

Incorrect data split ratio during model training, evaluation, validation, and test

Buy Now
Questions 21

You work at a gaming startup that has several terabytes of structured data in Cloud Storage. This data includes gameplay time data, user metadata, and game metadata. You want to build a model that recommends new games to users that requires the least amount of coding. What should you do?

Options:

A.

Load the data in BigQuery. Use BigQuery ML to train an Autoencoder model.

B.

Load the data in BigQuery. Use BigQuery ML to train a matrix factorization model.

C.

Read data to a Vertex Al Workbench notebook. Use TensorFlow to train a two-tower model.

D.

Read data to a Vertex Al Workbench notebook. Use TensorFlow to train a matrix factorization model.

Buy Now
Questions 22

You are responsible for building a unified analytics environment across a variety of on-premises data marts. Your company is experiencing data quality and security challenges when integrating data across the servers, caused by the use of a wide range of disconnected tools and temporary solutions. You need a fully managed, cloud-native data integration service that will lower the total cost of work and reduce repetitive work. Some members on your team prefer a codeless interface for building Extract, Transform, Load (ETL) process. Which service should you use?

Options:

A.

Dataflow

B.

Dataprep

C.

Apache Flink

D.

Cloud Data Fusion

Buy Now
Questions 23

Your organization’s marketing team is building a customer recommendation chatbot that uses a generative AI large language model (LLM) to provide personalized product suggestions in real time. The chatbot needs to access data from millions of customers, including purchase history, browsing behavior, and preferences. The data is stored in a Cloud SQL for PostgreSQL database. You need the chatbot response time to be less than 100ms. How should you design the system?

Options:

A.

Use BigQuery ML to fine-tune the LLM with the data in the Cloud SQL for PostgreSQL database, and access the model from BigQuery.

B.

Replicate the Cloud SQL for PostgreSQL database to AlloyDB. Configure the chatbot server to query AlloyDB.

C.

Transform relevant customer data into vector embeddings and store them in Vertex AI Search for retrieval by the LLM.

D.

Create a caching layer between the chatbot and the Cloud SQL for PostgreSQL database to store frequently accessed customer data. Configure the chatbot server to query the cache.

Buy Now
Questions 24

You work on the data science team at a manufacturing company. You are reviewing the company ' s historical sales data, which has hundreds of millions of records. For your exploratory data analysis, you need to calculate descriptive statistics such as mean, median, and mode; conduct complex statistical tests for hypothesis testing; and plot variations of the features over time You want to use as much of the sales data as possible in your analyses while minimizing computational resources. What should you do?

Options:

A.

Spin up a Vertex Al Workbench user-managed notebooks instance and import the dataset Use this data to create statistical and visual analyses

B.

Visualize the time plots in Google Data Studio. Import the dataset into Vertex Al Workbench user-managed notebooks Use this data to calculate the descriptive statistics and run the statistical analyses

C.

Use BigQuery to calculate the descriptive statistics. Use Vertex Al Workbench user-managed notebooks to visualize the time plots and run the statistical analyses.

D Use BigQuery to calculate the descriptive statistics, and use Google Data Studio to visualize the time plots. Use Vertex Al Workbench user-managed notebooks to run the statistical analyses.

Buy Now
Questions 25

You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.

The proposed architecture has the following flow:
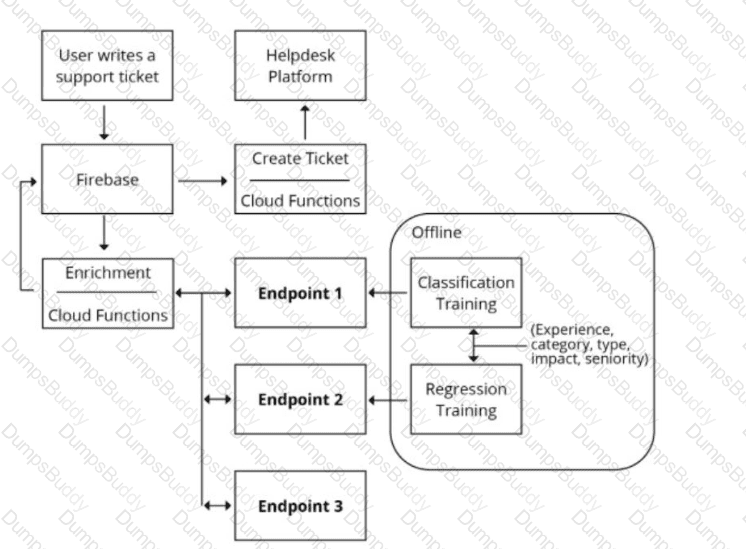
Professional-Machine-Learning-Engineer Question 25

Which endpoints should the Enrichment Cloud Functions call?

Options:

A.

1 = Vertex Al. 2 = Vertex Al. 3 = AutoML Natural Language

B.

1 = Vertex Al. 2 = Vertex Al. 3 = Cloud Natural Language API

C.

1 = Vertex Al. 2 = Vertex Al. 3 = AutoML Vision

D.

1 = Cloud Natural Language API. 2 = Vertex Al, 3 = Cloud Vision API

Buy Now
Questions 26

Your team has a model deployed to a Vertex Al endpoint You have created a Vertex Al pipeline that automates the model training process and is triggered by a Cloud Function. You need to prioritize keeping the model up-to-date, but also minimize retraining costs. How should you configure retraining ' ?

Options:

A.

Configure Pub/Sub to call the Cloud Function when a sufficient amount of new data becomes available.

B.

Configure a Cloud Scheduler job that calls the Cloud Function at a predetermined frequency that fits your team ' s budget.

C.

Enable model monitoring on the Vertex Al endpoint Configure Pub/Sub to call the Cloud Function when anomalies are detected.

D.

Enable model monitoring on the Vertex Al endpoint Configure Pub/Sub to call the Cloud Function when feature drift is detected.

Buy Now
Questions 27

You work for a gaming company that manages a popular online multiplayer game where teams with 6 players play against each other in 5-minute battles. There are many new players every day. You need to build a model that automatically assigns available players to teams in real time. User research indicates that the game is more enjoyable when battles have players with similar skill levels. Which business metrics should you track to measure your model’s performance? (Choose One Correct Answer)

Options:

A.

Average time players wait before being assigned to a team

B.

Precision and recall of assigning players to teams based on their predicted versus actual ability

C.

User engagement as measured by the number of battles played daily per user

D.

Rate of return as measured by additional revenue generated minus the cost of developing a new model

Buy Now
Questions 28

You have built a custom model that performs several memory-intensive preprocessing tasks before it makes a prediction. You deployed the model to a Vertex Al endpoint. and validated that results were received in a reasonable amount of time After routing user traffic to the endpoint, you discover that the endpoint does not autoscale as expected when receiving multiple requests What should you do?

Options:

A.

Use a machine type with more memory

B.

Decrease the number of workers per machine

C.

Increase the CPU utilization target in the autoscaling configurations

D.

Decrease the CPU utilization target in the autoscaling configurations

Buy Now
Questions 29

You are implementing a batch inference ML pipeline in Google Cloud. The model was developed using TensorFlow and is stored in SavedModel format in Cloud Storage You need to apply the model to a historical dataset containing 10 TB of data that is stored in a BigQuery table How should you perform the inference?

Options:

A.

Export the historical data to Cloud Storage in Avro format. Configure a Vertex Al batch prediction job to generate predictions for the exported data.

B.

Import the TensorFlow model by using the create model statement in BigQuery ML Apply the historical data to the TensorFlow model.

C.

Export the historical data to Cloud Storage in CSV format Configure a Vertex Al batch prediction job to generate predictions for the exported data.

D.

Configure a Vertex Al batch prediction job to apply the model to the historical data in BigQuery

Buy Now
Questions 30

You need to create a working environment in Vertex AI Workbench for a team of data scientists. Each data scientist has different VM CPU and RAM and package requirements, and will be assigned a personal notebook instance. You want each instance to have a custom set of packages pre-installed. Your company wants to minimize the running cost of notebook instances. How should you create the environment?

Options:

A.

Create Vertex AI Workbench instances based on a Deep Learning Containers container image. Disable idle shutdown of each instance.

B.

Create Vertex AI Workbench instances based on a Deep Learning Containers container image. Use n1-standard-4 as the default machine type. Verify idle shutdown of each instance.

C.

Create Vertex AI Workbench instances based on a custom container image derived from a Deep Learning Containers image. Verify idle shutdown of each instance.

D.

Create Vertex AI Workbench instances based on a custom container image derived from a Deep Learning Containers image. Use n1-standard-4 as the default machine type. Verify idle shutdown of each instance.

Buy Now
Questions 31

You are training an object detection machine learning model on a dataset that consists of three million X-ray images, each roughly 2 GB in size. You are using Vertex AI Training to run a custom training application on a Compute Engine instance with 32-cores, 128 GB of RAM, and 1 NVIDIA P100 GPU. You notice that model training is taking a very long time. You want to decrease training time without sacrificing model performance. What should you do?

Options:

A.

Increase the instance memory to 512 GB and increase the batch size.

B.

Replace the NVIDIA P100 GPU with a v3-32 TPU in the training job.

C.

Enable early stopping in your Vertex AI Training job.

D.

Use the tf.distribute.Strategy API and run a distributed training job.

Buy Now
Questions 32

You recently deployed a pipeline in Vertex Al Pipelines that trains and pushes a model to a Vertex Al endpoint to serve real-time traffic. You need to continue experimenting and iterating on your pipeline to improve model performance. You plan to use Cloud Build for CI/CD You want to quickly and easily deploy new pipelines into production and you want to minimize the chance that the new pipeline implementations will break in production. What should you do?

Options:

A.

Set up a CI/CD pipeline that builds and tests your source code If the tests are successful use the Google Cloud console to upload the built container to Artifact Registry and upload the compiled pipeline to Vertex Al Pipelines.

B.

Set up a CI/CD pipeline that builds your source code and then deploys built artifacts into a pre-production environment Run unit tests in the pre-production environment If the tests are successful deploy the pipeline to production.

C.

Set up a CI/CD pipeline that builds and tests your source code and then deploys built artifacts into a pre-production environment. After a successful pipeline run in the pre-production environment deploy the pipeline to production

D.

Set up a CI/CD pipeline that builds and tests your source code and then deploys built arrets into a pre-production environment After a successful pipeline run in the pre-production environment, rebuild the source code, and deploy the artifacts to production

Buy Now
Questions 33

You manage a team of data scientists who use a cloud-based backend system to submit training jobs. This system has become very difficult to administer, and you want to use a managed service instead. The data scientists you work with use many different frameworks, including Keras, PyTorch, theano, scikit-learn, and custom libraries. What should you do?

Options:

A.

Use the Vertex AI Training to submit training jobs using any framework.

B.

Configure Kubeflow to run on Google Kubernetes Engine and submit training jobs through TFJob.

C.

Create a library of VM images on Compute Engine, and publish these images on a centralized repository.

D.

Set up Slurm workload manager to receive jobs that can be scheduled to run on your cloud infrastructure.

Buy Now
Questions 34

You work with a team of researchers to develop state-of-the-art algorithms for financial analysis. Your team develops and debugs complex models in TensorFlow. You want to maintain the ease of debugging while also reducing the model training time. How should you set up your training environment?

Options:

A.

Configure a v3-8 TPU VM SSH into the VM to tram and debug the model.

B.

Configure a v3-8 TPU node Use Cloud Shell to SSH into the Host VM to train and debug the model.

C.

Configure a M-standard-4 VM with 4 NVIDIA P100 GPUs SSH into the VM and use

Parameter Server Strategy to train the model.

D.

Configure a M-standard-4 VM with 4 NVIDIA P100 GPUs SSH into the VM and use

MultiWorkerMirroredStrategy to train the model.

Buy Now
Questions 35

You work for a bank You have been asked to develop an ML model that will support loan application decisions. You need to determine which Vertex Al services to include in the workflow You want to track the model ' s training parameters and the metrics per training epoch. You plan to compare the performance of each version of the model to determine the best model based on your chosen metrics. Which Vertex Al services should you use?

Options:

A.

Vertex ML Metadata Vertex Al Feature Store, and Vertex Al Vizier

B.

Vertex Al Pipelines. Vertex Al Experiments, and Vertex Al Vizier

C.

Vertex ML Metadata Vertex Al Experiments, and Vertex Al TensorBoard

D.

Vertex Al Pipelines. Vertex Al Feature Store, and Vertex Al TensorBoard

Buy Now
Questions 36

One of your models is trained using data provided by a third-party data broker. The data broker does not reliably notify you of formatting changes in the data. You want to make your model training pipeline more robust to issues like this. What should you do?

Options:

A.

Use TensorFlow Data Validation to detect and flag schema anomalies.

B.

Use TensorFlow Transform to create a preprocessing component that will normalize data to the expected distribution, and replace values that don’t match the schema with 0.

C.

Use tf.math to analyze the data, compute summary statistics, and flag statistical anomalies.

D.

Use custom TensorFlow functions at the start of your model training to detect and flag known formatting errors.

Buy Now
Questions 37

You have a demand forecasting pipeline in production that uses Dataflow to preprocess raw data prior to model training and prediction. During preprocessing, you employ Z-score normalization on data stored in BigQuery and write it back to BigQuery. New training data is added every week. You want to make the process more efficient by minimizing computation time and manual intervention. What should you do?

Options:

A.

Normalize the data using Google Kubernetes Engine

B.

Translate the normalization algorithm into SQL for use with BigQuery

C.

Use the normalizer_fn argument in TensorFlow ' s Feature Column API

D.

Normalize the data with Apache Spark using the Dataproc connector for BigQuery

Buy Now
Questions 38

You are the Director of Data Science at a large company, and your Data Science team has recently begun using the Kubeflow Pipelines SDK to orchestrate their training pipelines. Your team is struggling to integrate their custom Python code into the Kubeflow Pipelines SDK. How should you instruct them to proceed in order to quickly integrate their code with the Kubeflow Pipelines SDK?

Options:

A.

Use the func_to_container_op function to create custom components from the Python code.

B.

Use the predefined components available in the Kubeflow Pipelines SDK to access Dataproc, and run the custom code there.

C.

Package the custom Python code into Docker containers, and use the load_component_from_file function to import the containers into the pipeline.

D.

Deploy the custom Python code to Cloud Functions, and use Kubeflow Pipelines to trigger the Cloud Function.

Buy Now
Questions 39

You are analyzing customer data for a healthcare organization that is stored in Cloud Storage. The data contains personally identifiable information (PII) You need to perform data exploration and preprocessing while ensuring the security and privacy of sensitive fields What should you do?

Options:

A.

Use the Cloud Data Loss Prevention (DLP) API to de-identify the PI! before performing data exploration and preprocessing.

B.

Use customer-managed encryption keys (CMEK) to encrypt the Pll data at rest and decrypt the Pll data during data exploration and preprocessing.

C.

Use a VM inside a VPC Service Controls security perimeter to perform data exploration and preprocessing.

D.

Use Google-managed encryption keys to encrypt the Pll data at rest, and decrypt the Pll data during data exploration and preprocessing.

Buy Now
Questions 40

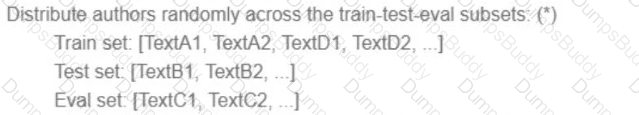
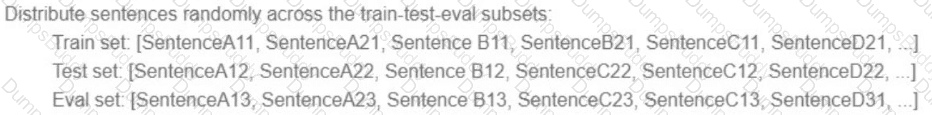
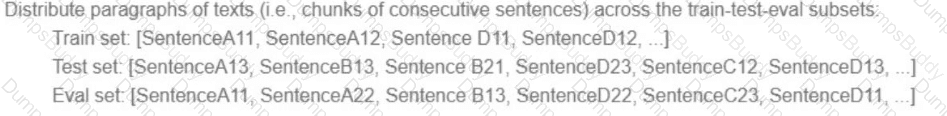
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this:
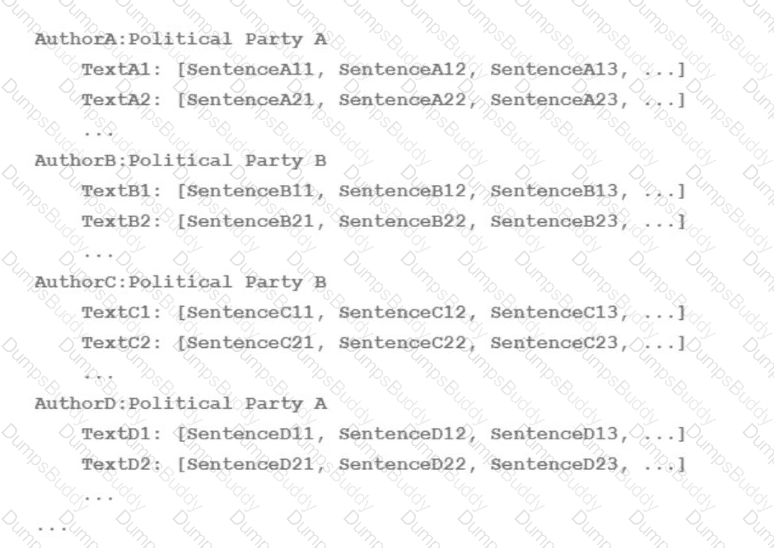
Professional-Machine-Learning-Engineer Question 40

You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets. How should you distribute the training examples across the train-test-eval subsets while maintaining the 80-10-10 proportion?

A)
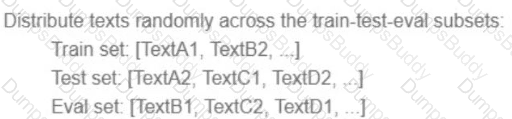
Professional-Machine-Learning-Engineer Question 40

B)

Professional-Machine-Learning-Engineer Question 40

C)

Professional-Machine-Learning-Engineer Question 40

D)

Professional-Machine-Learning-Engineer Question 40

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

Buy Now
Questions 41

You work for an online grocery store. You recently developed a custom ML model that recommends a recipe when a user arrives at the website. You chose the machine type on the Vertex Al endpoint to optimize costs by using the queries per second (QPS) that the model can serve, and you deployed it on a single machine with 8 vCPUs and no accelerators.

A holiday season is approaching and you anticipate four times more traffic during this time than the typical daily traffic You need to ensure that the model can scale efficiently to the increased demand. What should you do?

Options:

A.

1, Maintain the same machine type on the endpoint.

2 Set up a monitoring job and an alert for CPU usage

3 If you receive an alert add a compute node to the endpoint

B.

1 Change the machine type on the endpoint to have 32 vCPUs

2. Set up a monitoring job and an alert for CPU usage

3 If you receive an alert, scale the vCPUs further as needed

C.

1 Maintain the same machine type on the endpoint Configure the endpoint to enable autoscalling based on vCPU usage.

2 Set up a monitoring job and an alert for CPU usage

3 If you receive an alert investigate the cause

D.

1 Change the machine type on the endpoint to have a GPU_ Configure the endpoint to enable autoscaling based on the GPU usage.

2 Set up a monitoring job and an alert for GPU usage.

3 If you receive an alert investigate the cause.

Buy Now
Questions 42

Your team frequently creates new ML models and runs experiments. Your team pushes code to a single repository hosted on Cloud Source Repositories. You want to create a continuous integration pipeline that automatically retrains the models whenever there is any modification of the code. What should be your first step to set up the CI pipeline?

Options:

A.

Configure a Cloud Build trigger with the event set as " Pull Request "

B.

Configure a Cloud Build trigger with the event set as " Push to a branch "

C.

Configure a Cloud Function that builds the repository each time there is a code change.

D.

Configure a Cloud Function that builds the repository each time a new branch is created.

Buy Now
Questions 43

You are training a Resnet model on Al Platform using TPUs to visually categorize types of defects in automobile engines. You capture the training profile using the Cloud TPU profiler plugin and observe that it is highly input-bound. You want to reduce the bottleneck and speed up your model training process. Which modifications should you make to the tf .data dataset?

Choose 2 answers

Options:

A.

Use the interleave option for reading data

B.

Reduce the value of the repeat parameter

C.

Increase the buffer size for the shuffle option.

D.

Set the prefetch option equal to the training batch size

E.

Decrease the batch size argument in your transformation

Buy Now
Questions 44

You work for a hospital that wants to optimize how it schedules operations. You need to create a model that uses the relationship between the number of surgeries scheduled and beds used You want to predict how many beds will be needed for patients each day in advance based on the scheduled surgeries You have one year of data for the hospital organized in 365 rows

The data includes the following variables for each day

• Number of scheduled surgeries

• Number of beds occupied

• Date

You want to maximize the speed of model development and testing What should you do?

Options:

A.

Create a BigQuery table Use BigQuery ML to build a regression model, with number of beds as the target variable and number of scheduled surgeries and date features (such as day of week) as the predictors

B.

Create a BigQuery table Use BigQuery ML to build an ARIMA model, with number of beds as the target variable and date as the time variable.

C.

Create a Vertex Al tabular dataset Tram an AutoML regression model, with number of beds as the target variable and number of scheduled minor surgeries and date features (such as day of the week) as the predictors

D.

Create a Vertex Al tabular dataset Train a Vertex Al AutoML Forecasting model with number of beds as the target variable, number of scheduled surgeries as a covariate, and date as the time variable.

Buy Now
Questions 45

You are developing an image recognition model using PyTorch based on ResNet50 architecture. Your code is working fine on your local laptop on a small subsample. Your full dataset has 200k labeled images You want to quickly scale your training workload while minimizing cost. You plan to use 4 V100 GPUs. What should you do? (Choose Correct Answer and Give References and Explanation)

Options:

A.

Configure a Compute Engine VM with all the dependencies that launches the training Train your model with Vertex Al using a custom tier that contains the required GPUs.

B.

Package your code with Setuptools. and use a pre-built container Train your model with Vertex Al using a custom tier that contains the required GPUs.

C.

Create a Vertex Al Workbench user-managed notebooks instance with 4 V100 GPUs, and use it to train your model

D.

Create a Google Kubernetes Engine cluster with a node pool that has 4 V100 GPUs Prepare and submit a TFJob operator to this node pool.

Buy Now
Questions 46

You are developing an ML model in a Vertex Al Workbench notebook. You want to track artifacts and compare models during experimentation using different approaches. You need to rapidly and easily transition successful experiments to production as you iterate on your model implementation. What should you do?

Options:

A.

1 Initialize the Vertex SDK with the name of your experiment Log parameters and metrics for each experiment, and attach dataset and model artifacts as inputs and outputs to each execution.

2 After a successful experiment create a Vertex Al pipeline.

B.

1. Initialize the Vertex SDK with the name of your experiment Log parameters and metrics for each experiment, save your dataset to a Cloud Storage bucket and upload the models to Vertex Al Model Registry.

2 After a successful experiment create a Vertex Al pipeline.

C.

1 Create a Vertex Al pipeline with parameters you want to track as arguments to your Pipeline Job Use the Metrics. Model, and Dataset artifact types from the Kubeflow Pipelines DSL as the inputs and outputs of the components in your pipeline.

2. Associate the pipeline with your experiment when you submit the job.

D.

1 Create a Vertex Al pipeline Use the Dataset and Model artifact types from the Kubeflow Pipelines. DSL as the inputs and outputs of the components in your pipeline.

2. In your training component use the Vertex Al SDK to create an experiment run Configure the log_params and log_metrics functions to track parameters and metrics of your experiment.

Buy Now
Questions 47

You work for a company that sells corporate electronic products to thousands of businesses worldwide. Your company stores historical customer data in BigQuery. You need to build a model that predicts customer lifetime value over the next three years. You want to use the simplest approach to build the model and you want to have access to visualization tools. What should you do?

Options:

A.

Create a Vertex Al Workbench notebook to perform exploratory data analysis. Use IPython magics to create a new BigQuery table with input features Use the BigQuery console to run the create model statement Validate the results by using the ml. evaluate and ml. predict statements.

B.

Run the create model statement from the BigQuery console to create an AutoML model Validate the results by using the ml. evaluate and ml. predict statements.

C.

Create a Vertex Al Workbench notebook to perform exploratory data analysis and create input features Save the features as a CSV file in Cloud Storage Import the CSV file as a new BigQuery table Use the BigQuery console to run the create model statement Validate the results by using the ml. evaluate and ml. predict statements.

D.

Create a Vertex Al Workbench notebook to perform exploratory data analysis Use IPython magics to create a new BigQuery table with input features, create the model and validate the results by using the create model, ml. evaluates, and ml. predict statements.

Buy Now
Questions 48

You trained a text classification model. You have the following SignatureDefs:
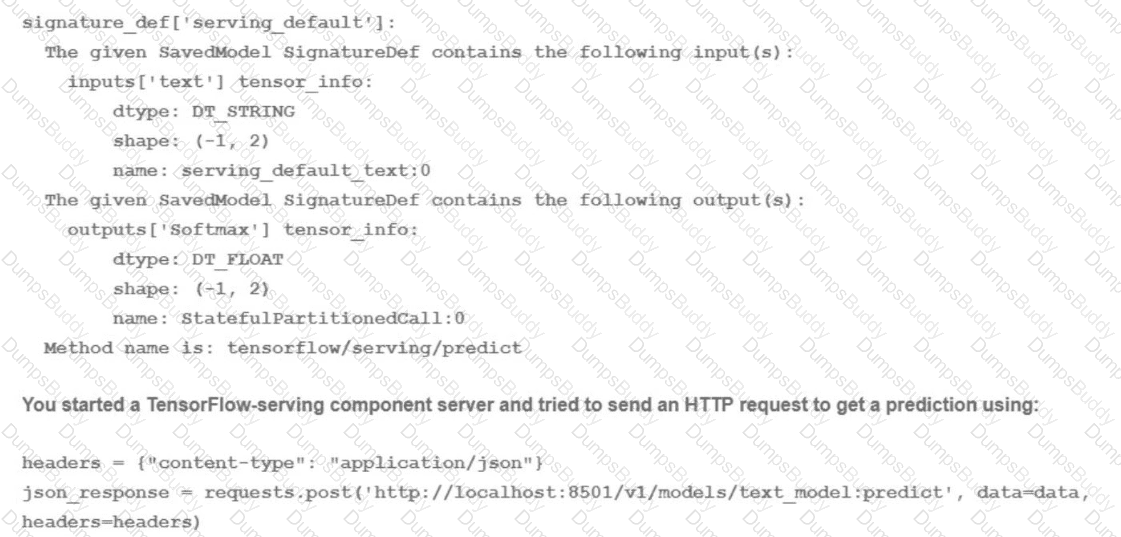
Professional-Machine-Learning-Engineer Question 48

What is the correct way to write the predict request?

Options:

A.

data = json.dumps({ " signature_name " : " serving_default ' \ " instances " : [fab ' , ' be1, ' cd ' ]]})

B.

data = json dumps({ " signature_name " : " serving_default " ! " instances " : [[ ' a ' , ' b ' , " c " , ' d ' , ' e ' , ' f ' ]]})

C.

data = json.dumps({ " signature_name " : " serving_default, " instances " : [[ ' a ' , ' b\ ' c ' 1, [d\ ' e\ T]]})

D.

data = json dumps({ " signature_name " : f,serving_default " , " instances " : [[ ' a ' , ' b ' ], [c\ ' d ' ], [ ' e\ T]]})

Buy Now
Questions 49

You developed a custom model by using Vertex Al to forecast the sales of your company s products based on historical transactional data You anticipate changes in the feature distributions and the correlations between the features in the near future You also expect to receive a large volume of prediction requests You plan to use Vertex Al Model Monitoring for drift detection and you want to minimize the cost. What should you do?

Options:

A.

Use the features for monitoring Set a monitoring- frequency value that is higher than the default.

B.

Use the features for monitoring Set a prediction-sampling-rare value that is closer to 1 than 0.

C.

Use the features and the feature attributions for monitoring. Set a monitoring-frequency value that is lower than the default.

D.

Use the features and the feature attributions for monitoring Set a prediction-sampling-rate value that is closer to 0 than 1.

Buy Now
Questions 50

You work on a growing team of more than 50 data scientists who all use AI Platform. You are designing a strategy to organize your jobs, models, and versions in a clean and scalable way. Which strategy should you choose?

Options:

A.

Set up restrictive IAM permissions on the AI Platform notebooks so that only a single user or group can access a given instance.

B.

Separate each data scientist’s work into a different project to ensure that the jobs, models, and versions created by each data scientist are accessible only to that user.

C.

Use labels to organize resources into descriptive categories. Apply a label to each created resource so that users can filter the results by label when viewing or monitoring the resources.

D.

Set up a BigQuery sink for Cloud Logging logs that is appropriately filtered to capture information about AI Platform resource usage. In BigQuery, create a SQL view that maps users to the resources they are using

Buy Now
Questions 51

You recently developed a deep learning model using Keras, and now you are experimenting with different training strategies. First, you trained the model using a single GPU, but the training process was too slow. Next, you distributed the training across 4 GPUs using tf.distribute.MirroredStrategy (with no other changes), but you did not observe a decrease in training time. What should you do?

Options:

A.

Distribute the dataset with tf.distribute.Strategy.experimental_distribute_dataset

B.

Create a custom training loop.

C.

Use a TPU with tf.distribute.TPUStrategy.

D.

Increase the batch size.

Buy Now
Questions 52

You recently trained a XGBoost model that you plan to deploy to production for online inference Before sending a predict request to your model ' s binary you need to perform a simple data preprocessing step This step exposes a REST API that accepts requests in your internal VPC Service Controls and returns predictions You want to configure this preprocessing step while minimizing cost and effort What should you do?

Options:

A.

Store a pickled model in Cloud Storage Build a Flask-based app packages the app in a custom container image, and deploy the model to Vertex Al Endpoints.

B.

Build a Flask-based app. package the app and a pickled model in a custom container image, and deploy the model to Vertex Al Endpoints.

C.

Build a custom predictor class based on XGBoost Predictor from the Vertex Al SDK. package it and a pickled model in a custom container image based on a Vertex built-in image, and deploy the model to Vertex Al Endpoints.

D.

Build a custom predictor class based on XGBoost Predictor from the Vertex Al SDK and package the handler in a custom container image based on a Vertex built-in container image Store a pickled model in Cloud Storage and deploy the model to Vertex Al Endpoints.

Buy Now
Questions 53

You are building a predictive maintenance model to preemptively detect part defects in bridges. You plan to use high definition images of the bridges as model inputs. You need to explain the output of the model to the relevant stakeholders so they can take appropriate action. How should you build the model?

Options:

A.

Use scikit-learn to build a tree-based model, and use SHAP values to explain the model output.

B.

Use scikit-lean to build a tree-based model, and use partial dependence plots (PDP) to explain the model output.

C.

Use TensorFlow to create a deep learning-based model and use Integrated Gradients to explain the model

output.

D.

Use TensorFlow to create a deep learning-based model and use the sampled Shapley method to explain the model output.

Buy Now
Questions 54

You work for an international manufacturing organization that ships scientific products all over the world Instruction manuals for these products need to be translated to 15 different languages Your organization ' s leadership team wants to start using machine learning to reduce the cost of manual human translations and increase translation speed. You need to implement a scalable solution that maximizes accuracy and minimizes operational overhead. You also want to include a process to evaluate and fix incorrect translations. What should you do?

Options:

A.

Create a workflow using Cloud Function Triggers Configure a Cloud Function that is triggered when documents are uploaded to an input Cloud Storage bucket Configure another Cloud Function that translates the documents using the Cloud Translation API and saves the translations to an output Cloud Storage bucket Use human reviewers to evaluate the incorrect translations.

B.

Create a Vertex Al pipeline that processes the documents1 launches an AutoML Translation training job evaluates the translations, and deploys the model to a Vertex Al endpoint with autoscaling and model monitoring When there is a predetermined skew between training and live data re-trigger the pipeline with the latest data.

C.

Use AutoML Translation to tram a model Configure a Translation Hub project and use the trained model to translate the documents Use human reviewers to evaluate the incorrect translations

D.

Use Vertex Al custom training jobs to fine-tune a state-of-the-art open source pretrained model with your data Deploy the model to a Vertex Al endpoint with autoscaling and model monitoring When there is a predetermined skew between the training and live data, configure a trigger to run another training job with the latest data.

Buy Now
Questions 55

During batch training of a neural network, you notice that there is an oscillation in the loss. How should you adjust your model to ensure that it converges?

Options:

A.

Increase the size of the training batch

B.

Decrease the size of the training batch

C.

Increase the learning rate hyperparameter

D.

Decrease the learning rate hyperparameter

Buy Now
Questions 56

You work for a large hotel chain and have been asked to assist the marketing team in gathering predictions for a targeted marketing strategy. You need to make predictions about user lifetime value (LTV) over the next 30 days so that marketing can be adjusted accordingly. The customer dataset is in BigQuery, and you are preparing the tabular data for training with AutoML Tables. This data has a time signal that is spread across multiple columns. How should you ensure that AutoML fits the best model to your data?

Options:

A.

Manually combine all columns that contain a time signal into an array Allow AutoML to interpret this array appropriately

Choose an automatic data split across the training, validation, and testing sets

B.

Submit the data for training without performing any manual transformations Allow AutoML to handle the appropriate

transformations Choose an automatic data split across the training, validation, and testing sets

C.

Submit the data for training without performing any manual transformations, and indicate an appropriate column as the Time column Allow AutoML to split your data based on the time signal provided, and reserve the more recent data for the validation and testing sets

D.

Submit the data for training without performing any manual transformations Use the columns that have a time signal to manually split your data Ensure that the data in your validation set is from 30 days after the data in your training set and that the data in your testing set is from 30 days after your validation set

Buy Now
Questions 57

You have been asked to develop an input pipeline for an ML training model that processes images from disparate sources at a low latency. You discover that your input data does not fit in memory. How should you create a dataset following Google-recommended best practices?

Options:

A.

Create a tf.data.Dataset.prefetch transformation

B.

Convert the images to tf .Tensor Objects, and then run Dataset. from_tensor_slices{).

C.

Convert the images to tf .Tensor Objects, and then run tf. data. Dataset. from_tensors ().

D.

Convert the images Into TFRecords, store the images in Cloud Storage, and then use the tf. data API to read the images for training

Buy Now
Questions 58

You have developed an AutoML tabular classification model that identifies high-value customers who interact with your organization ' s website.

You plan to deploy the model to a new Vertex Al endpoint that will integrate with your website application. You expect higher traffic to the website during

nights and weekends. You need to configure the model endpoint ' s deployment settings to minimize latency and cost. What should you do?

Options:

A.

Configure the model deployment settings to use an n1-standard-32 machine type.

B.

Configure the model deployment settings to use an n1-standard-4 machine type. Set the minReplicaCount value to 1 and the maxReplicaCount value to 8.

C.

Configure the model deployment settings to use an n1-standard-4 machine type and a GPU accelerator. Set the minReplicaCount value to 1 and the maxReplicaCount value to 4.

D.

Configure the model deployment settings to use an n1-standard-8 machine type and a GPU accelerator.

Buy Now
Questions 59

You work for a company that captures live video footage of checkout areas in their retail stores You need to use the live video footage to build a mode! to detect the number of customers waiting for service in near real time You want to implement a solution quickly and with minimal effort How should you build the model?

Options:

A.

Use the Vertex Al Vision Occupancy Analytics model.

B.

Use the Vertex Al Vision Person/vehicle detector model

C.

Train an AutoML object detection model on an annotated dataset by using Vertex AutoML

D.

Train a Seq2Seq+ object detection model on an annotated dataset by using Vertex AutoML

Buy Now
Questions 60

You work for a magazine distributor and need to build a model that predicts which customers will renew their subscriptions for the upcoming year. Using your company’s his torical data as your training set, you created a TensorFlow model and deployed it to AI Platform. You need to determine which customer attribute has the most predictive power for each prediction served by the model. What should you do?

Options:

A.

Use AI Platform notebooks to perform a Lasso regression analysis on your model, which will eliminate features that do not provide a strong signal.

B.

Stream prediction results to BigQuery. Use BigQuery’s CORR(X1, X2) function to calculate the Pearson correlation coefficient between each feature and the target variable.

C.

Use the AI Explanations feature on AI Platform. Submit each prediction request with the ‘explain’ keyword to retrieve feature attributions using the sampled Shapley method.

D.

Use the What-If tool in Google Cloud to determine how your model will perform when individual features are excluded. Rank the feature importance in order of those that caused the most significant performance drop when removed from the model.

Buy Now
Questions 61

You recently used BigQuery ML to train an AutoML regression model. You shared results with your team and received positive feedback. You need to deploy your model for online prediction as quickly as possible. What should you do?

Options:

A.

Retrain the model by using BigQuery ML. and specify Vertex Al as the model registry Deploy the model from Vertex Al Model Registry to a Vertex Al endpoint.

B.

Retrain the model by using Vertex Al Deploy the model from Vertex Al Model Registry to a Vertex Al endpoint.

C.

Alter the model by using BigQuery ML and specify Vertex Al as the model registry Deploy the model from Vertex Al Model Registry to a Vertex Al endpoint.

D.

Export the model from BigQuery ML to Cloud Storage Import the model into Vertex Al Model Registry Deploy the model to a Vertex Al endpoint.

Buy Now
Questions 62

You have written unit tests for a Kubeflow Pipeline that require custom libraries. You want to automate the execution of unit tests with each new push to your development branch in Cloud Source Repositories. What should you do?

Options:

A.

Write a script that sequentially performs the push to your development branch and executes the unit tests on Cloud Run

B.

Using Cloud Build, set an automated trigger to execute the unit tests when changes are pushed to your development branch.

C.

Set up a Cloud Logging sink to a Pub/Sub topic that captures interactions with Cloud Source Repositories Configure a Pub/Sub trigger for Cloud Run, and execute the unit tests on Cloud Run.

D.

Set up a Cloud Logging sink to a Pub/Sub topic that captures interactions with Cloud Source Repositories. Execute the unit tests using a Cloud Function that is triggered when messages are sent to the Pub/Sub topic

Buy Now
Questions 63

You are tasked with building an MLOps pipeline to retrain tree-based models in production. The pipeline will include components related to data ingestion, data processing, model training, model evaluation, and model deployment. Your organization primarily uses PySpark-based workloads for data preprocessing. You want to minimize infrastructure management effort. How should you set up the pipeline?

Options:

A.

Set up a TensorFlow Extended (TFX) pipeline on Vertex Al Pipelines to orchestrate the MLOps pipeline. Write a custom component for the PySpark-based workloads on Dataproc.

B.

Set up a Vertex Al Pipelines to orchestrate the MLOps pipeline. Use the predefined Dataproc component for the PySpark-based workloads.

C.

Set up Cloud Composer to orchestrate the MLOps pipeline. Use Dataproc workflow templates for the PySpark-based workloads in Cloud Composer.

D.

Set up Kubeflow Pipelines on Google Kubernetes Engine to orchestrate the MLOps pipeline. Write a custom component for the PySpark-based workloads on Dataproc.

Buy Now
Questions 64

You work for a bank with strict data governance requirements. You recently implemented a custom model to detect fraudulent transactions You want your training code to download internal data by using an API endpoint hosted in your projects network You need the data to be accessed in the most secure way, while mitigating the risk of data exfiltration. What should you do?

Options:

A.

Enable VPC Service Controls for peering’s, and add Vertex Al to a service perimeter

B.

Create a Cloud Run endpoint as a proxy to the data Use Identity and Access Management (1AM)

authentication to secure access to the endpoint from the training job.

C.

Configure VPC Peering with Vertex Al and specify the network of the training job

D.

Download the data to a Cloud Storage bucket before calling the training job

Buy Now
Questions 65

Your team needs to build a model that predicts whether images contain a driver ' s license, passport, or credit card. The data engineering team already built the pipeline and generated a dataset composed of 10,000 images with driver ' s licenses, 1,000 images with passports, and 1,000 images with credit cards. You now have to train a model with the following label map: [ ' driversjicense ' , ' passport ' , ' credit_card ' ]. Which loss function should you use?

Options:

A.

Categorical hinge

B.

Binary cross-entropy

C.

Categorical cross-entropy

D.

Sparse categorical cross-entropy

Buy Now
Questions 66

You recently joined a machine learning team that will soon release a new project. As a lead on the project, you are asked to determine the production readiness of the ML components. The team has already tested features and data, model development, and infrastructure. Which additional readiness check should you recommend to the team?

Options:

A.

Ensure that training is reproducible

B.

Ensure that all hyperparameters are tuned

C.

Ensure that model performance is monitored

D.

Ensure that feature expectations are captured in the schema

Buy Now
Questions 67

You have recently trained a scikit-learn model that you plan to deploy on Vertex Al. This model will support both online and batch prediction. You need to preprocess input data for model inference. You want to package the model for deployment while minimizing additional code What should you do?

Options:

A.

1 Upload your model to the Vertex Al Model Registry by using a prebuilt scikit-learn prediction container

2 Deploy your model to Vertex Al Endpoints, and create a Vertex Al batch prediction job that uses the instanceConfig.inscanceType setting to transform your input data

B.

1 Wrap your model in a custom prediction routine (CPR). and build a container image from the CPR local model

2 Upload your sci-kit learn model container to Vertex Al Model Registry

3 Deploy your model to Vertex Al Endpoints, and create a Vertex Al batch prediction job

C.

1. Create a custom container for your sci-kit learn model,

2 Define a custom serving function for your model

3 Upload your model and custom container to Vertex Al Model Registry

4 Deploy your model to Vertex Al Endpoints, and create a Vertex Al batch prediction job

D.

1 Create a custom container for your sci-kit learn model.

2 Upload your model and custom container to Vertex Al Model Registry

3 Deploy your model to Vertex Al Endpoints, and create a Vertex Al batch prediction job that uses the instanceConfig. instanceType setting to transform your input data

Buy Now
Questions 68

You work at a bank. You need to develop a credit risk model to support loan application decisions You decide to implement the model by using a neural network in TensorFlow Due to regulatory requirements, you need to be able to explain the models predictions based on its features When the model is deployed, you also want to monitor the model ' s performance overtime You decided to use Vertex Al for both model development and deployment What should you do?

Options:

A.

Use Vertex Explainable Al with the sampled Shapley method, and enable Vertex Al Model Monitoring to

check for feature distribution drift.

B.

Use Vertex Explainable Al with the sampled Shapley method, and enable Vertex Al Model Monitoring to

check for feature distribution skew.

C.

Use Vertex Explainable Al with the XRAI method, and enable Vertex Al Model Monitoring to check for feature distribution drift.

D.

Use Vertex Explainable Al with the XRAI method and enable Vertex Al Model Monitoring to check for feature distribution skew.

Buy Now
Questions 69

You work for a company that sells corporate electronic products to thousands of businesses worldwide. Your company stores historical customer data in BigQuery. You need to build a model that predicts customer lifetime value over the next three years. You want to use the simplest approach to build the model. What should you do?

Options:

A.

Access BigQuery Studio in the Google Cloud console. Run the create model statement in the SQL editor to create an ARIMA model.

B.

Create a Vertex Al Workbench notebook. Use IPython magic to run the create model statement to create an ARIMA model.

C.

Access BigQuery Studio in the Google Cloud console. Run the create model statement in the SQL editor to create an AutoML regression model.

D.

Create a Vertex Al Workbench notebook. Use IPython magic to run the create model statement to create an AutoML regression model.

Buy Now
Questions 70

You are an ML engineer at a manufacturing company. You need to build a model that identifies defects in products based on images of the product taken at the end of the assembly line. You want your model to preprocess the images with lower computation to quickly extract features of defects in products. Which approach should you use to build the model?

Options:

A.

Reinforcement learning

B.

Recommender system

C.

Recurrent Neural Networks (RNN)

D.

Convolutional Neural Networks (CNN)

Buy Now
Questions 71

You trained a model on data stored in a Cloud Storage bucket. The model needs to be retrained frequently in Vertex AI Training using the latest data in the bucket. Data preprocessing is required prior to retraining. You want to build a simple and efficient near-real-time ML pipeline in Vertex AI that will preprocess the data when new data arrives in the bucket. What should you do?

Options:

A.

Create a pipeline using the Vertex AI SDK. Schedule the pipeline with Cloud Scheduler to preprocess the new data in the bucket. Store the processed features in Vertex AI Feature Store.

B.

Create a Cloud Run function that is triggered when new data arrives in the bucket. The function initiates a Vertex AI Pipeline to preprocess the new data and store the processed features in Vertex AI Feature Store.

C.

Build a Dataflow pipeline to preprocess the new data in the bucket and store the processed features in BigQuery. Configure a cron job to trigger the pipeline execution.

D.

Use the Vertex AI SDK to preprocess the new data in the bucket prior to each model retraining. Store the processed features in BigQuery.

Buy Now
Questions 72

You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run. How should you set up your experiments?

Options:
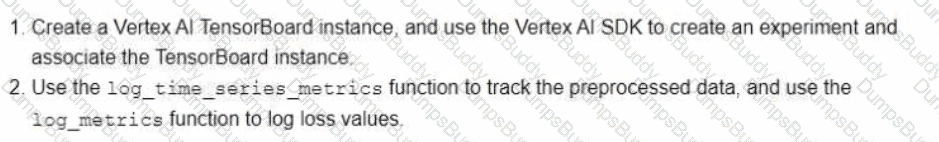
A.
B.
C.
D.

72

Buy Now
Questions 73

You work for a pet food company that manages an online forum Customers upload photos of their pets on the forum to share with others About 20 photos are uploaded daily You want to automatically and in near real time detect whether each uploaded photo has an animal You want to prioritize time and minimize cost of your application development and deployment What should you do?

Options:

A.

Send user-submitted images to the Cloud Vision API Use object localization to identify all objects in the image and compare the results against a list of animals.

B.

Download an object detection model from TensorFlow Hub. Deploy the model to a Vertex Al endpoint. Send new user-submitted images to the model endpoint to classify whether each photo has an animal.

C.

Manually label previously submitted images with bounding boxes around any animals Build an AutoML object detection model by using Vertex Al Deploy the model to a Vertex Al endpoint Send new user-submitted images to your model endpoint to detect whether each photo has an animal.

D.

Manually label previously submitted images as having animals or not Create an image dataset on Vertex Al Train a classification model by using Vertex AutoML to distinguish the two classes Deploy the model to a Vertex Al endpoint Send new user-submitted images to your model endpoint to classify whether each photo has an animal.

Buy Now
Questions 74

You recently deployed a scikit-learn model to a Vertex Al endpoint You are now testing the model on live production traffic While monitoring the endpoint. you discover twice as many requests per hour than expected throughout the day You want the endpoint to efficiently scale when the demand increases in the future to prevent users from experiencing high latency What should you do?

Options:

A.

Deploy two models to the same endpoint and distribute requests among them evenly.

B.

Configure an appropriate minReplicaCount value based on expected baseline traffic.

C.

Set the target utilization percentage in the autcscalir.gMetricspecs configuration to a higher value

D.

Change the model ' s machine type to one that utilizes GPUs.

Buy Now
Questions 75

You are working on a system log anomaly detection model for a cybersecurity organization. You have developed the model using TensorFlow, and you plan to use it for real-time prediction. You need to create a Dataflow pipeline to ingest data via Pub/Sub and write the results to BigQuery. You want to minimize the serving latency as much as possible. What should you do?

Options:

A.

Containerize the model prediction logic in Cloud Run, which is invoked by Dataflow.

B.

Load the model directly into the Dataflow job as a dependency, and use it for prediction.

C.

Deploy the model to a Vertex AI endpoint, and invoke this endpoint in the Dataflow job.

D.

Deploy the model in a TFServing container on Google Kubernetes Engine, and invoke it in the Dataflow job.

Buy Now
Questions 76

You work for an organization that operates a streaming music service. You have a custom production model that is serving a " next song " recommendation based on a user’s recent listening history. Your model is deployed on a Vertex Al endpoint. You recently retrained the same model by using fresh data. The model received positive test results offline. You now want to test the new model in production while minimizing complexity. What should you do?

Options:

A.

Create a new Vertex Al endpoint for the new model and deploy the new model to that new endpoint Build a service to randomly send 5% of production traffic to the new endpoint Monitor end-user metrics such as listening time If end-user metrics improve between models over time gradually increase the percentage of production traffic sent to the new endpoint.

B.

Capture incoming prediction requests in BigQuery Create an experiment in Vertex Al Experiments Run batch predictions for both models using the captured data Use the user ' s selected song to compare the models performance side by side If the new models performance metrics are better than the previous model deploy the new model to production.

C.

Deploy the new model to the existing Vertex Al endpoint Use traffic splitting to send 5% of production traffic to the new model Monitor end-user metrics, such as listening time If end-user metrics improve between models over time, gradually increase the percentage of production traffic sent to the new model.

D.

Configure a model monitoring job for the existing Vertex Al endpoint. Configure the monitoring job to detect prediction drift, and set a threshold for alerts Update the model on the endpoint from the previous model to the new model If you receive an alert of prediction drift, revert to the previous model.

Buy Now
Questions 77

You are developing an ML model intended to classify whether X-Ray images indicate bone fracture risk. You have trained on Api Resnet architecture on Vertex AI using a TPU as an accelerator, however you are unsatisfied with the trainning time and use memory usage. You want to quickly iterate your training code but make minimal changes to the code. You also want to minimize impact on the models accuracy. What should you do?

Options:

A.

Configure your model to use bfloat16 instead float32

B.

Reduce the global batch size from 1024 to 256

C.

Reduce the number of layers in the model architecture

D.

Reduce the dimensions of the images used un the model

Buy Now
Questions 78

You work for a company that is developing an application to help users with meal planning You want to use machine learning to scan a corpus of recipes and extract each ingredient (e g carrot, rice pasta) and each kitchen cookware (e.g. bowl, pot spoon) mentioned Each recipe is saved in an unstructured text file What should you do?

Options:

A.

Create a text dataset on Vertex Al for entity extraction Create two entities called ingredient " and cookware " and label at least 200 examples of each entity Train an AutoML entity extraction model to extract occurrences of these entity types Evaluate performance on a holdout dataset.

B.

Create a multi-label text classification dataset on Vertex Al Create a test dataset and label each recipe that corresponds to its ingredients and cookware Train a multi-class classification model Evaluate the model’s performance on a holdout dataset.

C.

Use the Entity Analysis method of the Natural Language API to extract the ingredients and cookware from each recipe Evaluate the model ' s performance on a prelabeled dataset.

D.

Create a text dataset on Vertex Al for entity extraction Create as many entities as there are different ingredients and cookware Train an AutoML entity extraction model to extract those entities Evaluate the models performance on a holdout dataset.

Buy Now
Questions 79

You have created multiple versions of an ML model and have imported them to Vertex AI Model Registry. You want to perform A/B testing to identify the best-performing model using the simplest approach. What should you do?

Options:

A.

Split incoming traffic among separate Cloud Run instances of deployed models. Monitor the performance of each version using Cloud Monitoring.

B.

Split incoming traffic to distribute prediction requests among the versions. Monitor the performance of each version using Looker Studio dashboards that compare logged data for each version.

C.

Split incoming traffic among Google Kubernetes Engine (GKE) clusters and use Traffic Director to distribute prediction requests to different versions. Monitor the performance of each version using Cloud Monitoring.

D.

Split incoming traffic to distribute prediction requests among the versions. Monitor the performance of each version using Vertex AI’s built-in monitoring tools.

Buy Now
Questions 80

You have recently used TensorFlow to train a classification model on tabular data You have created a Dataflow pipeline that can transform several terabytes of data into training or prediction datasets consisting of TFRecords. You now need to productionize the model, and you want the predictions to be automatically uploaded to a BigQuery table on a weekly schedule. What should you do?

Options:

A.

Import the model into Vertex Al and deploy it to a Vertex Al endpoint On Vertex Al Pipelines create a pipeline that uses the Dataf lowPythonJobop and the Mcdei3archPredictoc components.

B.

Import the model into Vertex Al and deploy it to a Vertex Al endpoint Create a Dataflow pipeline that reuses the data processing logic sends requests to the endpoint and then uploads predictions to a BigQuery table.

C.

Import the model into Vertex Al On Vertex Al Pipelines, create a pipeline that uses the DatafIowPythonJobOp and the ModelBatchPredictOp components.

D.

Import the model into BigQuery Implement the data processing logic in a SQL query On Vertex Al Pipelines create a pipeline that uses the BigqueryQueryJobop and the EigqueryPredictModejobOp components.

Buy Now
Questions 81

You developed an ML model with Al Platform, and you want to move it to production. You serve a few thousand queries per second and are experiencing latency issues. Incoming requests are served by a load balancer that distributes them across multiple Kubeflow CPU-only pods running on Google Kubernetes Engine (GKE). Your goal is to improve the serving latency without changing the underlying infrastructure. What should you do?

Options:

A.

Significantly increase the max_batch_size TensorFlow Serving parameter

B.

Switch to the tensorflow-model-server-universal version of TensorFlow Serving

C.

Significantly increase the max_enqueued_batches TensorFlow Serving parameter

D.

Recompile TensorFlow Serving using the source to support CPU-specific optimizations Instruct GKE to choose an appropriate baseline minimum CPU platform for serving nodes

Buy Now
Questions 82

You are investigating the root cause of a misclassification error made by one of your models. You used Vertex Al Pipelines to tram and deploy the model. The pipeline reads data from BigQuery. creates a copy of the data in Cloud Storage in TFRecord format trains the model in Vertex Al Training on that copy, and deploys the model to a Vertex Al endpoint. You have identified the specific version of that model that misclassified: and you need to recover the data this model was trained on. How should you find that copy of the data ' ?

Options:

A.

Use Vertex Al Feature Store Modify the pipeline to use the feature store; and ensure that all training data is stored in it Search the feature store for the data used for the training.

B.

Use the lineage feature of Vertex Al Metadata to find the model artifact Determine the version of the model and identify the step that creates the data copy, and search in the metadata for its location.

C.

Use the logging features in the Vertex Al endpoint to determine the timestamp of the models deployment Find the pipeline run at that timestamp Identify the step that creates the data copy; and search in the logs for its location.

D.

Find the job ID in Vertex Al Training corresponding to the training for the model Search in the logs of that job for the data used for the training.

Buy Now
Questions 83

You have trained an XGBoost model that you plan to deploy on Vertex Al for online prediction. You are now uploading your model to Vertex Al Model Registry, and you need to configure the explanation method that will serve online prediction requests to be returned with minimal latency. You also want to be alerted when feature attributions of the model meaningfully change over time. What should you do?

Options:

A.

1 Specify sampled Shapley as the explanation method with a path count of 5.

2 Deploy the model to Vertex Al Endpoints.

3. Create a Model Monitoring job that uses prediction drift as the monitoring objective.

B.

1 Specify Integrated Gradients as the explanation method with a path count of 5.

2 Deploy the model to Vertex Al Endpoints.

3. Create a Model Monitoring job that uses prediction drift as the monitoring objective.

C.

1. Specify sampled Shapley as the explanation method with a path count of 50.

2. Deploy the model to Vertex Al Endpoints.

3. Create a Model Monitoring job that uses training-serving skew as the monitoring objective.

D.

1 Specify Integrated Gradients as the explanation method with a path count of 50.

2. Deploy the model to Vertex Al Endpoints.

3 Create a Model Monitoring job that uses training-serving skew as the monitoring objective.

Buy Now
Questions 84

Your data science team needs to rapidly experiment with various features, model architectures, and hyperparameters. They need to track the accuracy metrics for various experiments and use an API to query the metrics over time. What should they use to track and report their experiments while minimizing manual effort?

Options:

A.

Use Kubeflow Pipelines to execute the experiments Export the metrics file, and query the results using the Kubeflow Pipelines API.

B.

Use Al Platform Training to execute the experiments Write the accuracy metrics to BigQuery, and query the results using the BigQueryAPI.

C.

Use Al Platform Training to execute the experiments Write the accuracy metrics to Cloud Monitoring, and query the results using the Monitoring API.

D.

Use Al Platform Notebooks to execute the experiments. Collect the results in a shared Google Sheets file, and query the results using the Google Sheets API

Buy Now
Questions 85

You are collaborating on a model prototype with your team. You need to create a Vertex Al Workbench environment for the members of your team and also limit access to other employees in your project. What should you do?

Options:

A.

1. Create a new service account and grant it the Notebook Viewer role.

2 Grant the Service Account User role to each team member on the service account.

3 Grant the Vertex Al User role to each team member.

4. Provision a Vertex Al Workbench user-managed notebook instance that uses the new service account.

B.

1. Grant the Vertex Al User role to the default Compute Engine service account.

2. Grant the Service Account User role to each team member on the default Compute Engine service account.

3. Provision a Vertex Al Workbench user-managed notebook instance that uses the default Compute Engine service account.

C.

1 Create a new service account and grant it the Vertex Al User role.

2 Grant the Service Account User role to each team member on the service account.

3. Grant the Notebook Viewer role to each team member.

4 Provision a Vertex Al Workbench user-managed notebook instance that uses the new service account.

D.

1 Grant the Vertex Al User role to the primary team member.

2. Grant the Notebook Viewer role to the other team members.

3. Provision a Vertex Al Workbench user-managed notebook instance that uses the primary user’s account.

Buy Now
Questions 86

You need to develop an image classification model by using a large dataset that contains labeled images in a Cloud Storage Bucket. What should you do?

Options:

A.

Use Vertex Al Pipelines with the Kubeflow Pipelines SDK to create a pipeline that reads the images from Cloud Storage and trains the model.

B.

Use Vertex Al Pipelines with TensorFlow Extended (TFX) to create a pipeline that reads the images from Cloud Storage and trams the model.

C.

Import the labeled images as a managed dataset in Vertex Al: and use AutoML to tram the model.

D.

Convert the image dataset to a tabular format using Dataflow Load the data into BigQuery and use BigQuery ML to tram the model.

Buy Now
Questions 87

Your data science team has requested a system that supports scheduled model retraining, Docker containers, and a service that supports autoscaling and monitoring for online prediction requests. Which platform components should you choose for this system?

Options:

A.

Vertex AI Pipelines and App Engine

B.

Vertex AI Pipelines, Vertex AI Prediction, and Vertex AI Model Monitoring

C.

Cloud Composer, BigQuery ML, and Vertex AI Prediction

D.

Cloud Composer, Vertex AI Training with custom containers, and App Engine

Buy Now
Questions 88

You are creating a social media app where pet owners can post images of their pets. You have one million user uploaded images with hashtags. You want to build a comprehensive system that recommends images to users that are similar in appearance to their own uploaded images.

What should you do?

Options:

A.

Download a pretrained convolutional neural network, and fine-tune the model to predict hashtags based on the input images. Use the predicted hashtags to make recommendations.

B.

Retrieve image labels and dominant colors from the input images using the Vision API. Use these properties and the hashtags to make recommendations.

C.

Use the provided hashtags to create a collaborative filtering algorithm to make recommendations.

D.

Download a pretrained convolutional neural network, and use the model to generate embeddings of the input images. Measure similarity between embeddings to make recommendations.

Buy Now
Exam Name: Google Professional Machine Learning Engineer
Last Update: Oct 8, 2026
Questions: 296

PDF + Testing Engine

$134.99

Testing Engine

$99.99

PDF (Q&A)

$84.99